NVIDIA open-weights Nemotron 3.5 Transcribe for ASR, translation, and speakers
NVIDIA released open-weight Nemotron 3.5 Transcribe on Hugging Face (~34B total / ~4.3B active) for offline recordings: the card claims 40-language transcription for up to about one hour, with text instructions selecting verbatim, written, speaker-attributed, translation, and related modes. License is OpenMDW-1.1 for commercial or non-commercial use; it is not a real-time streaming model.
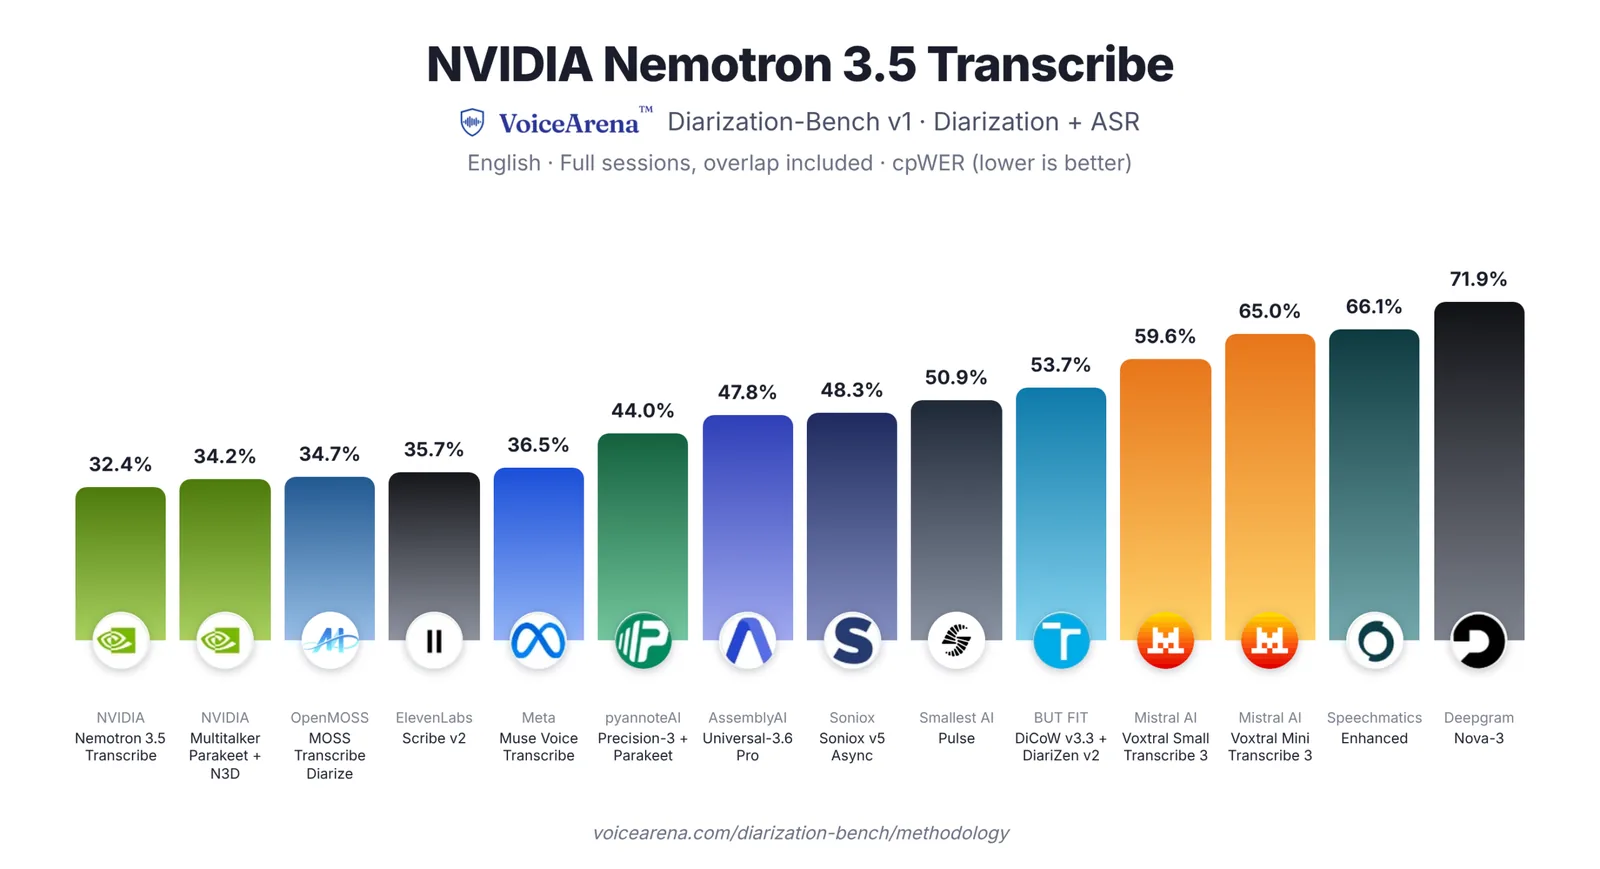
NVIDIA published NVIDIA-Nemotron-3.5-Transcribe-30B-A4B on Hugging Face. The model card describes an open-weight offline speech/audio model: a Mamba-2–Transformer hybrid MoE with a parallel expert encoder, ~34B total parameters including the audio encoder and ~4.3B active, 65,536-token context, recordings up to one hour, and BF16 plus FP8/NVFP4 variants. Tasks include verbatim/written transcription, contextual and speaker-attributed/rich transcription, speech translation, language ID, and audio question answering. The license is OpenMDW-1.1; the card says it is ready for commercial or non-commercial use.
The Decoder reports 40 transcription languages, translation for 31 languages to/from English, speaker identification in 13 languages, up to about one hour and eight speakers, with natural-language instructions (and optional term hints) controlling output style. On efficiency, Decoder cites under three minutes for 100 hours of audio on an RTX PRO 6000 Blackwell Server Edition at NVFP4; the model card cites up to about 2,238× real time with the NIM at NVFP4. The card’s Results at a Glance are labeled as captured on 12 October 2026 and should be read as publisher-reported benchmark snapshots.
Alongside the model, Decoder says NVIDIA is releasing Granary v2 (~844,000 hours across 48 languages, multiple transcript styles). Both the card and Decoder stress the offline (non-real-time) design; feature coverage varies by language; audio QA training is English-skewed; users should spot-check names, speaker changes, and answers. Weights and datasets are on Hugging Face with a demo and fine-tuning guides. Unlike pairing Nemotron 3 Diarization with a separate ASR model, Transcribe combines those jobs but does not claim live streaming.
Sources
- nvidia/NVIDIA-Nemotron-3.5-Transcribe-30B-A4B — NVIDIA (Hugging Face)
- Nvidia's open Nemotron 3.5 Transcribe combines transcription, translation, and speaker recognition — The Decoder