Inception launches Mercury 3: claims Luna/Haiku parity at ~1,068 tok/s
Inception Labs released diffusion LLM Mercury 3, saying it matches or beats GPT-6 Luna and Claude Haiku 5.5 on benchmarks while running ~1,068 tokens/s on NVIDIA GPUs (about 4–8× faster), with 1M context and list pricing of $0.20/$0.70 per million tokens (50% off at launch to $0.10/$0.35).
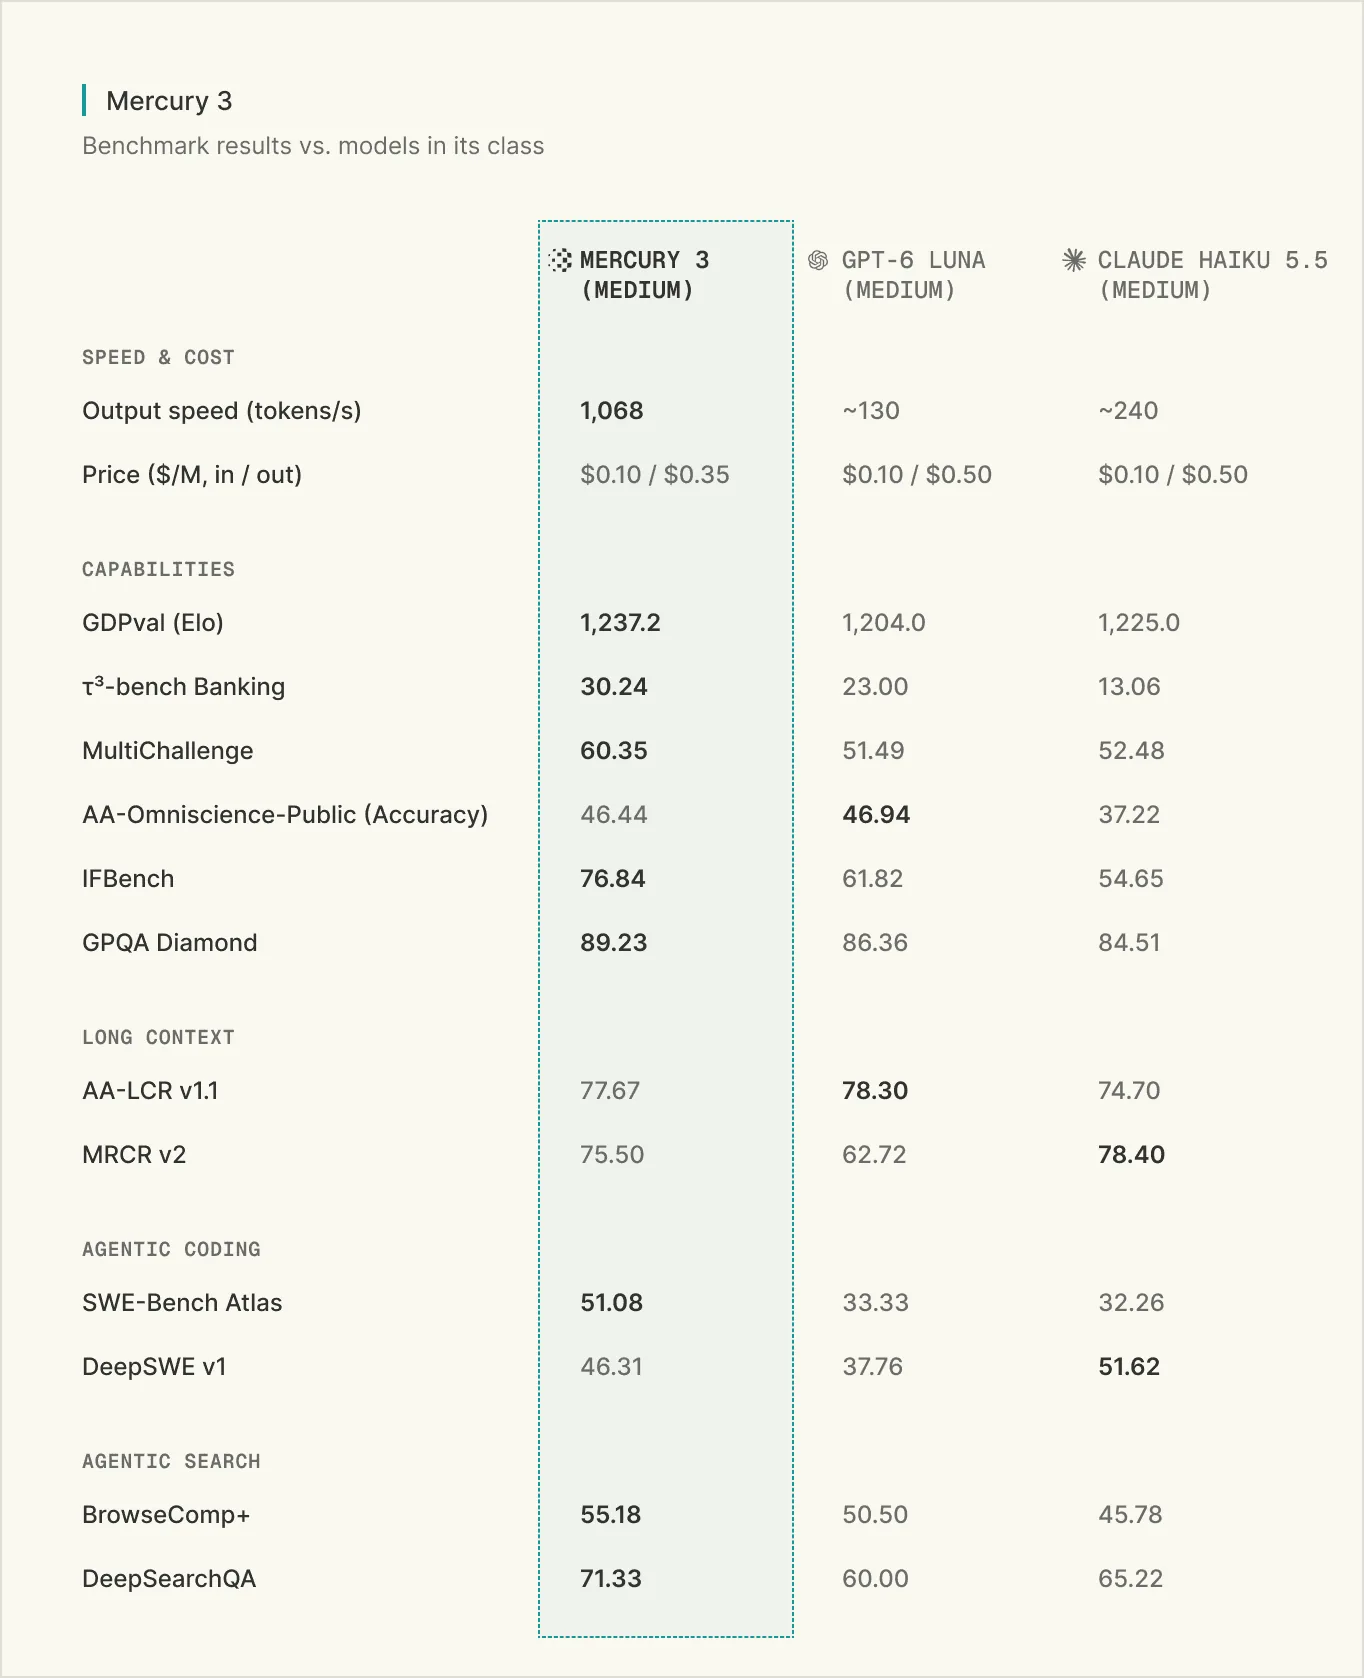
Inception Labs says Mercury 3 is its most capable diffusion LLM to date. At a glance it claims quality on par or better than speed-optimized frontier models such as GPT-6 Luna and Claude Haiku 5.5; 1,068 tokens per second on NVIDIA GPUs; 1M tokens of context (up from 260K on Mercury 2.5); and list prices of $0.20 input / $0.70 output per million tokens, with a 50% launch discount to $0.10 / $0.35 and cached tokens at 90% off the input price. The post says Mercury 3 is more than 40× larger than Mercury 1 and that benchmark “intelligence” rose about 3× from Mercury 1 (mini)—vendor claims.
Mercury 3 is available on the Inception API Platform and through OpenRouter, Baseten, and Vercel, with OpenAI API compatibility and a stated 100 million free tokens for API trials. The portfolio also includes Mercury Voice for low-latency voice and Mercury Decide, which Inception says outperforms Jev on JevBench and LegalBench. Early-access use cases cited include browser agents, interactive education, real-time search, and support; partner-quoted Mind2Web and glasses latency figures are third-party or vendor-reported.
Sources
- Introducing Mercury 3 — Inception Labs