DeepSeek open-sources DeepInfer, its production inference framework, starting with V4.1-Flash on NVIDIA SM100 and Ascend 950
DeepSeek has released DeepInfer on GitHub under Apache-2.0, describing it as the inference framework behind its large-scale production services. This release offers offline inference, supports DeepSeek-V4.1-Flash first and runs on NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs, but omits the KV cache system, prefill/decode disaggregation and load balancing a full service needs.
DeepSeek published the DeepInfer repository under its deepseek-ai GitHub organization. The README calls it the high-performance inference framework that powers DeepSeek's large-scale production services; this open-source release provides offline inference with the core features needed for serving at scale, under the Apache License 2.0. The first supported model is DeepSeek-V4.1-Flash, with DeepSeek-V4.1-Flash-1017 on Hugging Face as the default checkpoint.
Listed features include optimized kernels and sampler runtime (built on DeepSeek's FlashMLA, DeepGEMM and DeepEP libraries plus TileLang kernels), attention data parallelism and MoE expert parallelism with load balancing, DSpark draft decoding with confidence-scheduled verification, bounded sliding-window replay, asynchronous scheduling, batch-invariant inference, deterministic sampling and structured outputs; batch invariance and deterministic sampling are NVIDIA-only. Supported hardware is NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs, on Linux with Python 3.12 and CUDA 13 or CANN 9.2.
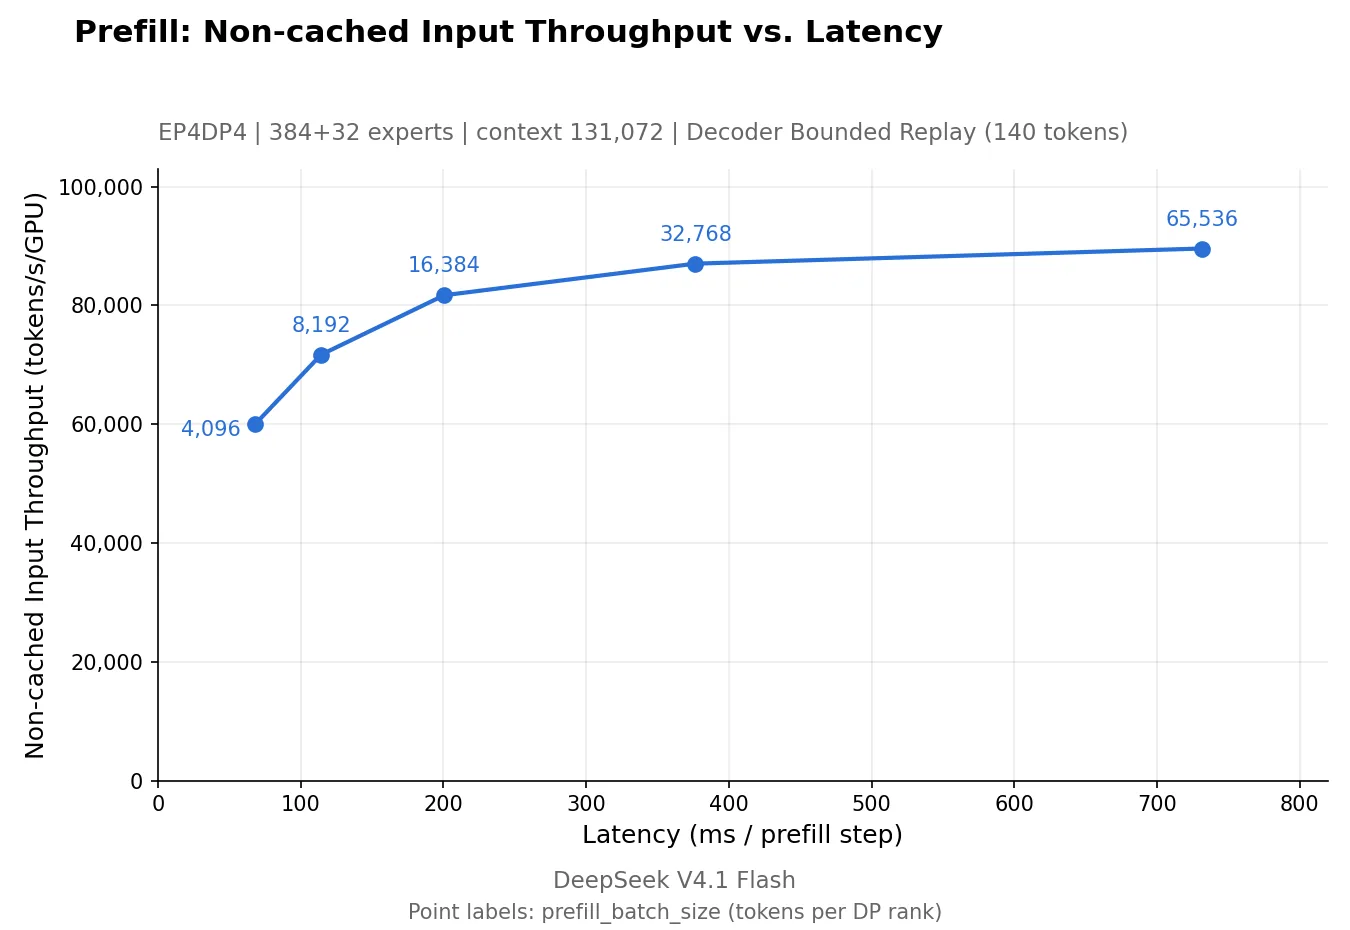
The repository says a KV cache system, vision-encoder/prefill/decode disaggregation and load balancing across data-parallel replicas are not included, so for now it is a reusable engine core rather than a ready-made online service. The README's throughput charts were measured by DeepSeek on 4 SM100 GPUs for prefill and 64 for decode. The project credits vLLM as its original main base, with inspiration from SGLang and TensorRT-LLM.
Sources
- DeepInfer: High-performance, large-scale inference framework for DeepSeek models — DeepSeek-AI(GitHub)