Liquid AI releases open d1 weights, adding an experimental audio model for local decisions
Liquid AI released downloadable d1-3B and experimental d1-omni-600M weights on October 7, enabling local structured decisions from text, images or speech. The models return answers without generating prose; audio is offered only in the smaller experimental model, with limits on inputs and training coverage.
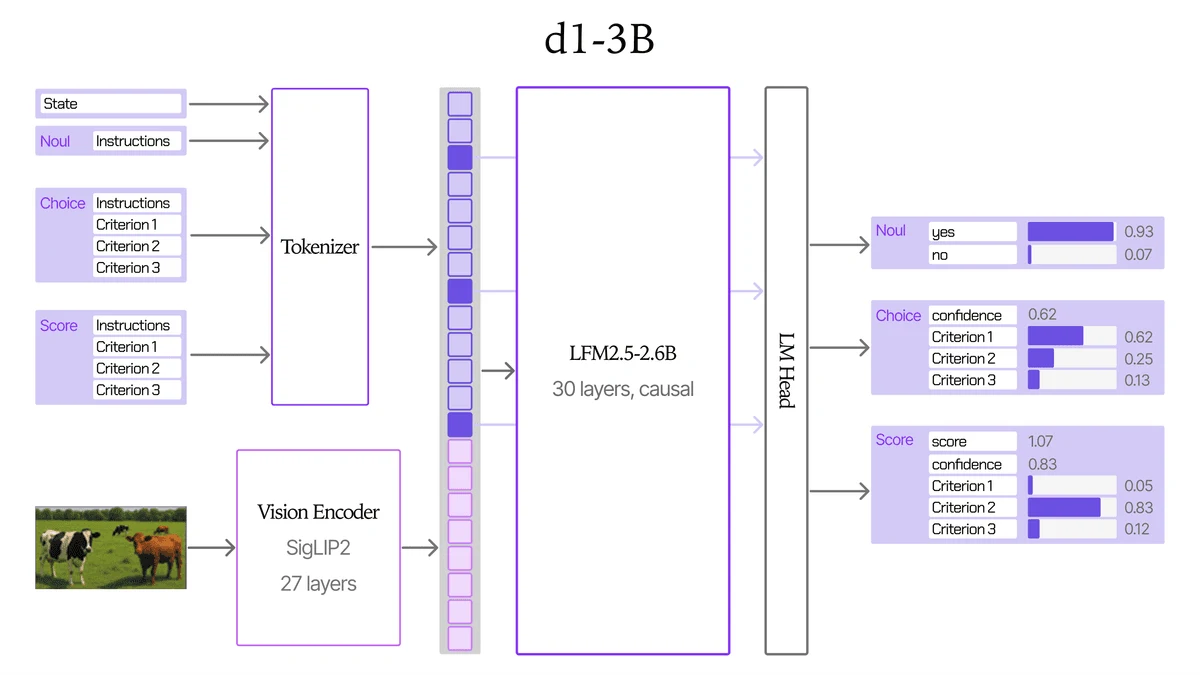
These models read the input and specified questions in one pass and return structured answers such as yes/no, a choice or a rating, with zero output tokens. They are not chat models and do not write prose. Liquid AI lists routing and triage, moderation, intent classification, agent guardrails and visual inspection as uses: steps where an answer can already be expressed as an option or a score.
d1-3B is built on LFM2.5-VL-3B, has 3.12B parameters and accepts text and images with a 32,768-token context. The smaller d1-omni-600M has 587M parameters and adds an audio path. Its 16,384-position context covers text, images and audio together; with images, the state and question text are cut to 896 tokens.
d1-omni-600M remains an experimental early research release. A request can contain images or audio, but not both. Speech clips are capped at 30 seconds, and audio training used requests between an English speaker and an assistant; that does not establish speech performance in Chinese or other languages. Liquid AI has not reported inference speeds for this smaller model.
Liquid AI reports 48.57 for d1-3B on the public split of Decision Index 0.2.1, above the comparison’s 47.11 for Decider 35B-A3B; d1-omni-600M scores 15.95. The model cards say the company used the official scorer for d1 rather than submitting leaderboard results, while the other models’ figures come from the public leaderboard. These are vendor evaluations of specific decision tasks, not general chatbot rankings.
The latency figures have specific conditions. For warm, single-question calls with one request at a time, the company reports 8 ms for d1-3B on an RTX 4090. GPU tests use bf16 and the median of 20 runs; the RTX 4090 also uses CUDA graphs optimization, without which the single question takes 16 ms. Reported single-question results on Jetson AGX Thor, AGX Orin and Orin Nano are 16, 26 and 50 ms, respectively. These numbers do not generalize to arbitrary images, long inputs, concurrent loads or d1-omni-600M.
Both models’ weights are available on Hugging Face for local use, alongside official browser demos. The model cards’ Transformers path requires version 5.14 or later for d1-3B and 5.15 or later for d1-omni-600M, with loading of repository-supplied code enabled.
Sources
- Multimodal open d1 decision models for the edge — Liquid AI
- Open d1: Edge decision models for text, vision, and audio — Liquid AI 模型与工程博客(网页)
- LiquidAI/d1-3B · Hugging Face — Liquid AI
- LiquidAI/d1-omni-600M · Hugging Face — Liquid AI