Meta details Prometheus: Ohio gigawatt-scale cluster targeting ~1M GPUs
Meta’s engineering blog describes Prometheus, its gigawatt-scale supercluster in New Albany, Ohio: phase one is complete and trained the Muse family (including Muse Wonder), with continued scale-out toward roughly 1 million GPUs and closed-loop liquid cooling.
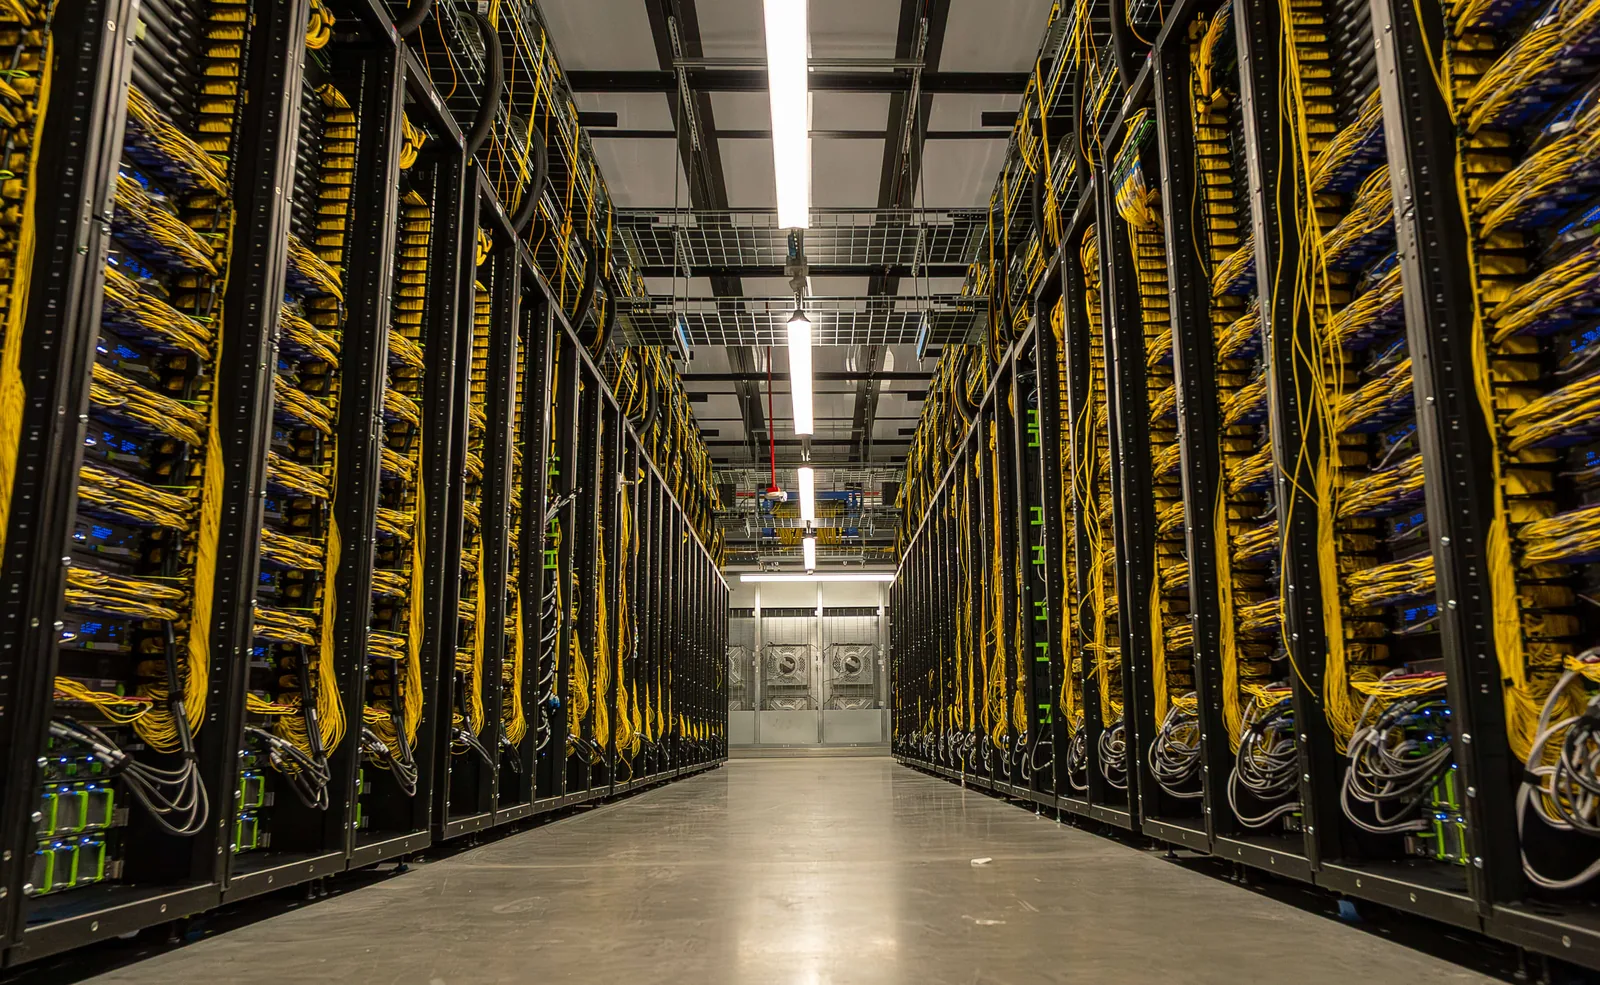
Engineering at Meta says Prometheus is its most ambitious AI infrastructure project to date, located in New Albany, Ohio—a site that ran conventional web traffic two years ago and has been rebuilt for frontier training. Phase one is already complete and was used to train Muse foundational models, including Muse Wonder. Today the cluster spans hundreds of thousands of GPUs across interconnected buildings; at full scale Meta targets roughly 1 million distributed GPUs, with closed-loop liquid cooling called out for efficiency.
On stability, Meta claims more than 85% goodput for Muse Wonder pre-training and more than 90% for RL, with wall-clock MTBI around 47k GPU hours later raised above 54k after firmware and fleet changes. Two NVIDIA platforms are deployed now—Catalina (GB200 NVL72 Ariel, two-rack 72-GPU domain with 800G per GPU) and Clemente (GB300 NVL72, single-rack 72 GPUs, 288 GB HBM per GPU)—with a Vera Rubin NVL72 generation arriving soon. Networking describes building fabrics interconnecting up to 20,736 GPUs and a Backend Aggregation spanning 2 km to over 100 km. All figures are Meta’s claims.
Sources
- Inside Prometheus: Meta’s Journey to a Gigawatt-Scale Supercluster — Engineering at Meta